A newly discovered prime number makes its debut

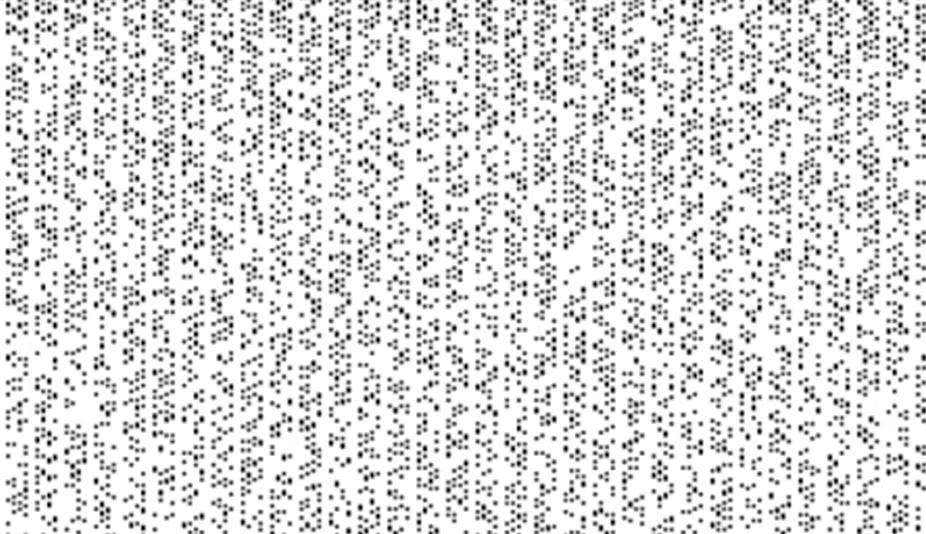
The distribution of prime numbers from 1 to 76,800, from left to right and top to bottom. A black pixel means that the number is first, while a white pixel means that it is not.

On December 26, 2017, J. Pace, G. Woltman, S. Kurowski, A. Blosser, and their co-authors announced the discovery of a new prime number): 2⁷⁷²³²⁹¹⁷-1. It’s an excellent opportunity to take a small tour through the wonderful world of prime numbers to see how this result was achieved and why it is so interesting.

A prime number is one that is divisible only by itself and the number 1, that is, essentially a number that has no divisor. Some speak of prime numbers as the atoms of the mathematical universe, others as precious stones.

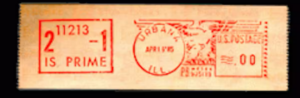
US stamp featuring the prime number 2¹¹²¹³-1. Author provided, CC BY

It is to Euclid that we owe the first two definitions of a prime number:

  • Any number is the unique product of prime factors.
  • They are infinite in number. The demonstration of this result is regarded as the first proof by absurdity: Suppose there is only a finite number of prime numbers, so they are all smaller than an integer n. Any integer greater than n would therefore be divisible by a prime number less than n. However, the number (2 * 3 * … * n) + 1 is not divisible by any integer from 2 to n since the remainder of the division is always 1 – a contradiction of the preceding sentence.

Eratosthenes, who lived from -276 to -194, proposed a process that allows us to find all prime numbers less than a given natural number N. The process consists of eliminating from a table integers from 2 to N that are multiples of those numbers. By deleting all the multiples, there remain only integers that are not multiples of any integer, and so are prime numbers. The search for efficient algorithms is an active research topic – for example for the Lucas-Lehmer test.

After the Greek era, there was a long dark period that lasted until the end of the 16th century and the arrival of French theologian and mathematician Marin Mersenne (1588-1648). He was an advocate of Catholic orthodoxy, yet also believed that religion must welcome any updated truth. He was a Cartesian and translator of Galileo.

Mersenne was looking for a formula that would generate all the prime numbers. In particular, he studied the numbers Mp = 2p-1, where p is prime. These numbers are now called Mersenne numbers or Mersenne primes. In 1644 he wrote that Mp is prime for p = 2, 3, 5, 7, 13, 17, 19, 31, 67, 127, 257, and compound – in other words, non-prime – for the other 44 lower p values at 257. These definition actually commits five errors: M61, M89 and M107 are prime, while M67 and M257 are not.

The new prime number discovered at the very end of 2017 corresponds to M77232917. It has 23,249,425 digits – almost a million digits more than the previous record-holding prime. If the number were contained by a document written in the font Times New Roman with a point size of 10 and standard page margins, it would fill 3,845 pages.

The official date of discovery of a prime number is the day that someone declares the result. This is in keeping with tradition: M4253 is reputed not to have one because in 1961 the American mathematician Alexander Hurwitz read a printer output from the end forward, and found M4423 a few seconds before seeing M4253. The previous Mersenne number also had a complicated history: the computer reported the result to the server on September 17, 2015, but a bug blocked the email. The prime number remained unnoticed until January 7, 2016.

Quantum cryptography

We often refer to the use of prime numbers in cryptography, but they’re too big to be really useful. (There is hope that quantum cryptography will change things.) Historically, Mersenne’s search for prime numbers has been used as a test for computer hardware. In 2016, the premium95 community discovered a flaw in Intel’s Skylake CPU as well as many PCs. This prime number was found as part of the Great Internet Mersenne Prime Search Project (GIMPS).

2⁷⁷²³²⁹¹⁷-1 is the 50th Mersenne prime and if the challenge to discover the 51st tempts you, the verification program is available to all – and there’s even a $3,000 prize.

For more insights like this, visit our website at www.international-maths-challenge.com.
Credit of the article given to Avner Bar-Hen


The Mathematics of (Hacking) Passwords

Credit: Gaetan Charbonneau Getty Images

The science and art of password setting and cracking continues to evolve, as does the war between password users and abusers

At one time or another, we have all been frustrated by trying to set a password, only to have it rejected as too weak. We are also told to change our choices regularly. Obviously such measures add safety, but how exactly?

I will explain the mathematical rationale for some standard advice, including clarifying why six characters are not enough for a good password and why you should never use only lowercase letters. I will also explain how hackers can uncover passwords even when stolen data sets lack them.

Choose#W!sely@*

Here is the logic behind setting hack-resistant passwords. When you are asked to create a password of a certain length and combination of elements, your choice will fit into the realm of all unique options that conform to that rule—into the “space” of possibilities. For example, if you were told to use six lowercase letters—such as, afzjxd, auntie, secret, wwwwww—the space would contain 266, or 308,915,776, possibilities. In other words, there are 26 possible choices for the first letter, 26 possible choices for the second, and so forth. These choices are independent: you do not have to use different letters, so the size of the password space is the product of the possibilities, or 26 x 26 x 26 x 26 x 26 x 26 = 266.

If you are told to select a 12-character password that can include uppercase and lowercase letters, the 10 digits and 10 symbols (say, !, @, #, $, %, ^, &, ?, / and +), you would have 72 possibilities for each of the 12 characters of the password. The size of the possibility space would then be 7212 (19,408,409,961,765,342,806,016, or close to 19 x 1021).

That is more than 62 trillion times the size of the first space. A computer running through all the possibilities for your 12-character password one by one would take 62 trillion times longer. If your computer spent a second visiting the six-character space, it would have to devote two million years to examining each of the passwords in the 12-character space. The multitude of possibilities makes it impractical for a hacker to carry out a plan of attack that might have been feasible for the six-character space.

Calculating the size of these spaces by computer usually involves counting the number of binary digits in the number of possibilities. That number, N, is derived from this formula: 1 + integer(log2(N)). In the formula, the value of log2(N) is a real number with many decimal places, such as log2(266) = 28.202638…. The “integer” in the formula indicates that the decimal portion of that log value is omitted, rounding down to a whole number—as in integer(28.202638… 28). For the example of six lowercase letters above, the computation results in 29 bits; for the more complex, 12-character example, it is 75 bits. (Mathematicians refer to the possibility spaces as having entropy of 29 and 75 bits, respectively.) The French National Cybersecurity Agency (ANSSI) recommends spaces having a minimum of 100 bits when it comes to passwords or secret keys for encryption systems that absolutely must be secure. Encryption involves representing data in a way that ensures it cannot be retrieved unless a recipient has a secret code-breaking key. In fact, the agency recommends a possibility space of 128 bits to guarantee security for several years. It considers 64 bits to be very small (very weak); 64 to 80 bits to be small; and 80 to 100 bits to be medium (moderately strong).

Moore’s law (which says that the computer-processing power available at a certain price doubles roughly every two years) explains why a relatively weak password will not suffice for long-term use: over time computers using brute force can find passwords faster. Although the pace of Moore’s law appears to be decreasing, it is wise to take it into account for passwords that you hope will remain secure for a long time.

For a truly strong password as defined by ANSSI, you would need, say, a sequence of 16 characters, each taken from a set of 200 characters. This would make a 123-bit space, which would render the password close to impossible to memorize. Therefore, system designers are generally less demanding and accept low- or medium-strength passwords. They insist on long ones only when the passwords are automatically generated by the system, and users do not have to remember them.

There are other ways to guard against password cracking. The simplest is well known and used by credit cards: after three unsuccessful attempts, access is blocked. Alternative ideas have also been suggested, such as doubling the waiting time after each successive failed attempt but allowing the system to reset after a long period, such as 24 hours. These methods, however, are ineffective when an attacker is able to access the system without being detected or if the system cannot be configured to interrupt and disable failed attempts.

How Long Does It Take to Search All Possible Passwords?

For a password to be difficult to crack, it should be chosen randomly from a large set, or “space,” of possibilities. The size, T, of the possibility space is based on the length, A, of the list of valid characters in the password and the number of characters, N, in the password.

The size of this space (T = AN) may vary considerably.

Each of the following examples specifies values of A, N, T and the number of hours, D, that hackers would have to spend to try every permutation of characters one by one. X is the number of years that will have to pass before the space can be checked in less than one hour, assuming that Moore’s law (the doubling of computing capacity every two years) remains valid. I also assume that in 2019, a computer can explore a billion possibilities per second. I represent this set of assumptions with the following three relationships and consider five possibilities based on values of A and N:


Relationships

T = AN
D = T/(109 × 3,600)
X = 2 log2[T/(109 × 3,600)]

Results

_________________________________

If A = 26 and N = 6, then T = 308,915,776
D = 0.0000858 computing hour
X = 0; it is already possible to crack all passwords in the space in under an hour

_________________________________

If A = 26 and N = 12, then T = 9.5 × 10¹⁶
D = 26,508 computing hours
X = 29 years before passwords can be cracked in under an hour

_________________________________

If A = 100 and N = 10, then T = 1020
D = 27,777,777 computing hours
X = 49 years before passwords can be cracked in under an hour

_________________________________

If A = 100 and N = 15, then T = 1030
D = 2.7 × 10¹⁷ computing hours
X = 115 years before passwords can be cracked in under an hour

________________________________

If A = 200 and N = 20, then T = 1.05 × 1046
D = 2.7 × 1033 computing hours
X = 222 years before passwords can be cracked in under an hour

Weaponizing Dictionaries and Other Hacker Tricks

Quite often an attacker succeeds in obtaining encrypted passwords or password “fingerprints” (which I will discuss more fully later) from a system. If the hack has not been detected, the interloper may have days or even weeks to attempt to derive the actual passwords.

To understand the subtle processes exploited in such cases, take another look at the possibility space. When I spoke earlier of bit size and password space (or entropy), I implicitly assumed that the user consistently chooses passwords at random. But typically the choice is not random: people tend to select a password they can remember (locomotive) rather than an arbitrary string of characters (xdichqewax).

This practice poses a serious problem for security because it makes passwords vulnerable to so-called dictionary attacks. Lists of commonly used passwords have been collected and classified according to how frequently they are used. Attackers attempt to crack passwords by going through these lists systematically. This method works remarkably well because, in the absence of specific constraints, people naturally choose simple words, surnames, first names and short sentences, which considerably limits the possibilities. In other words, the nonrandom selection of passwords essentially reduces possibility space, which decreases the average number of attempts needed to uncover a password.

If you use password or iloveyou, you are not as clever as you thought! Of course, lists differ according to the country where they are collected and the Web sites involved; they also vary over time.

For four-digit passwords (for example, the PIN code of SIM cards on smartphones), the results are even less imaginative. In 2013, based on a collection of 3.4 million passwords each containing four digits, the DataGenetics Web site reported that the most commonly used four-digit sequence (representing 11 percent of choices) was 1234, followed by 1111 (6 percent) and 0000 (2 percent). The least-used four-digit password was 8068. Careful, though, this ranking may no longer be true now that the result has been published. The 8068 choice appeared only 25 times among the 3.4-million four-digit sequences in the database, which is much less than the 340 uses that would have occurred if each four-digit combination had been used with the same frequency. The first 20 series of four digits are: 1234; 1111; 0000; 1212; 7777; 1004; 2000; 4444; 2222; 6969; 9999; 3333; 5555; 6666; 1122; 1313; 8888; 4321; 2001; 1010.

Even without a password dictionary, using differences in frequency of letter use (or double letters) in a language makes it possible to plan an effective attack. Some attack methods also take into account that, to facilitate memorization, people may choose passwords that have a certain structure—such as A1=B2=C3, AwX2AwX2 or O0o.lli. (which I used for a long time)—or that are derived by combining several simple strings, such as password123 or johnABC0000. Exploiting such regularities makes it possible to for hackers to speed up detection.

Advice for Web Sites

Web sites, too, follow various rules of thumb. The National Institute of Standards and Technology recently published a notice recommending the use of dictionaries to filter users’ password choices.

Among the rules that a good Web server designer absolutely must adhere to is, do not store plaintext lists of usernames and passwords on the computer used to operate the Web site.

The reason is obvious: hackers could access the computer containing this list, either because the site is poorly protected or because the system or processor contains a serious flaw unknown to anyone except the attackers (a so-called zero-day flaw), who can exploit it.

One alternative is to encrypt the passwords on the server: use a secret code that transforms them via an encryption key into what will appear to be random character sequences to anyone who does not possess the decryption key. This method works, but it has two disadvantages. First, it requires decrypting the stored password every time to compare it with the user’s entry, which is inconvenient. Second, and more seriously, the decryption necessary for this comparison requires storing the decryption key in the Web site computer’s memory. This key may therefore be detected by an attacker, which brings us back to the original problem.

A better way to store passwords is through what are called hash functions that produce “fingerprints.” For any data in a file—symbolized as F—a hash function generates a fingerprint. (The process is also called condensing or hashing.) The fingerprint—h(F)—is a fairly short word associated with F but produced in such a way that, in practice, it is impossible to deduce F from h(F). Hash functions are said to be one-way: getting from F to h(F) is easy; getting from h(F) to F is practically impossible. In addition, the hash functions used have the characteristic that even if it is possible for two data inputs, F and F’, to have the same fingerprint (known as a collision), in practice for a given F, it is almost impossible to find an F’ with a fingerprint identical to F.

Using such hash functions allows passwords to be securely stored on a computer. Instead of storing the list of paired usernames and passwords, the server stores only the list of username/fingerprint pairs.

When a user wishes to connect, the server will read the individual’s password, compute the fingerprint and determine whether it corresponds to the list of stored username/fingerprint pairs associated with that username. That maneuver frustrates hackers because even if they have managed to access the list, they will be unable to derive the users’ passwords, inasmuch as it is practically impossible to go from fingerprint to password. Nor can they generate another password with an identical fingerprint to fool the server because it is practically impossible to create collisions.

For more insights like this, visit our website at www.international-maths-challenge.com.

Credit of the article given to Jean-Paul Delahaye

Mathematics: forget simplicity, the abstract is beautiful – and important

Shutterstock

Why is mathematics so complicated? It’s a question many students will ask while grappling with a particularly complex calculus problem – and their teachers will probably echo while setting or marking tests.

It wasn’t always this way. Many fields of mathematics germinated from the study of real world problems, before the underlying rules and concepts were identified. These rules and concepts were then defined as abstract structures. For instance, algebra, the part of mathematics in which letters and other general symbols are used to represent numbers and quantities in formulas and equations was born from solving problems in arithmetic. Geometry emerged as people worked to solve problems dealing with distances and area in the real world.

That process of moving from the concrete to the abstract scenario is known, appropriately enough, as abstraction. Through abstraction, the underlying essence of a mathematical concept can be extracted. People no longer have to depend on real world objects, as was once the case, to solve a mathematical puzzle. They can now generalise to have wider applications or by matching it to other structures can illuminate similar phenomena. An example is the adding of integers, fractions, complex numbers, vectors and matrices. The concept is the same, but the applications are different.

This evolution was necessary for the development of mathematics, and important for other scientific disciplines too.

Why is this important? Because the growth of abstraction in maths gave disciplines like chemistry, physics, astronomy, geology, meteorology the ability to explain a wide variety of complex physical phenomena that occur in nature. If you grasp the process of abstraction in mathematics, it will equip you to better understand abstraction occurring in other tough science subjects like chemistry or physics.

From the real world to the abstract

The earliest example of abstraction was when humans counted before symbols existed. A sheep herder, for instance, needed to keep track of his flock of sheep without having any sort of symbolic system akin to numbers. So how did he do this to ensure that none of his sheep wandered away or got stolen?

One solution is to obtain a big supply of stones. He then moved the sheep one-by-one into an enclosed area. Each time a sheep passed, he placed a stone in a pile. Once all the sheep had passed, he got rid of the extra stones and was left with a pile of stones representing his flock.

Every time he needed to count the sheep, he removed the stones from his pile; one for each sheep. If he had stones left over, it means some sheep had wandered away or perhaps been stolen. This one-to-one correspondence helped the shepherd to keep track of his flock.

Today, we use the Arabic numbers (also known as the Hindu-Arabic numerals): 0,1,2,3,4,5,6,7,8,9 to represent any integer, that is any whole number.

This is another example of abstraction, and it’s powerful. It means we’re able to handle any amount of sheep, regardless of how many stones we have. We’ve moved from real-world objects – stones, sheep – to the abstract. There is real strength in this: we’ve created a space where the rules are minimalistic, yet the games that can be played are endless.

Another advantage of abstraction is that it reveals a deeper connection between different fields of mathematics. Results in one field can suggest concepts and ideas to be explored in a related field. Occasionally, methods and techniques developed in one field can be directly applied to another field to create similar results.

Tough concepts, better teaching

Of course, abstraction also has its disadvantages. Some of the mathematical subjects taught at university level – Calculus, Real Analysis, Linear Algebra, Topology, Category Theory, Functional Analysis and Set Theory among them – are very advanced examples of abstraction.

These concepts can be quite difficult to learn. They’re often tough to visualise and their rules rather unintuitive to manipulate or reason with. This means students need a degree of mathematical maturity to process the shift from the concrete to the abstract.

Many high school kids, particularly from developing countries, come to university with an undeveloped level of intellectual maturity to handle abstraction. This is because of the way mathematics was taught at high school. I have seen many students struggling, giving up or not even attempting to study mathematics because they weren’t given the right tools at school level and they think that they just “can’t do maths”.

Teachers and lecturers can improve this abstract thinking by being aware of abstractions in their subject and learning to demonstrate abstract concepts through concrete examples. Experiments are also helpful to familiarise and assure students of an abstract concept’s solidity.

This teaching principle is applied in some school systems, such as Montessori, to help children improve their abstract thinking. Not only does this guide them better through the maze of mathematical abstractions but it can be applied to other sciences as well.

For more insights like this, visit our website at www.international-maths-challenge.com.
Credit of the article given to Harry Zandberg Wiggins


The Ditherer’s Mean

Credit: Roy Scott/Getty Images

How to calculate an average if you’re indecisive

So you’ve got some numbers, and you want to produce one number that represents their typical value. If you’ve taken a little bit of math or statistics, you might reach for the mean—the arithmetic mean, to be precise. Add the numbers together and divide by the number of numbers you have. Easy enough.

But perhaps you’re a bit of a Chidi, and furthermore you made the mistake of learning about the geometric mean at some point. The geometric mean is another measure of central tendency, as statisticians say. The geometric mean is like the arithmetic mean, but you change addition to multiplication and division to taking roots. To find the geometric mean of two numbers, multiply them together and take the square root of their product. (This operation can only be performed on two numbers that are either both positive or both negative. But the world is negative enough. Let’s just think about positive numbers!) True to its name, this mean has a nice geometric interpretation: it is the side length of a square with the same area as a rectangle having your two numbers as side lengths. To find the geometric mean of a lot of numbers—let’s say n of them—multiply them all together and take the nth root.

Knowing about both the arithmetic and geometric means, you are wracked with internal turmoil: Which mean will best represent your numbers?

The arithmetic mean is nice. It seems very balanced and equitable. But the geometric mean has its merits as well. It is a useful tool when you’re working with processes that work multiplicatively instead of additively, like interest rates. It pulls larger numbers closer to smaller numbers more than the arithmetic mean does, whether you are taking the geometric mean of just two numbers or many numbers. The geometric mean might be a better representative than the arithmetic mean or even the median for a data set that has a lot of smaller values and a few large ones—say, income distributions.

Which will it be? Decisions are so hard!

Why not both?

The arithmetic-geometric mean lets you find a number between your two favorite positive numbers that is a compromise between the arithmetic and geometric means, letting your inner Chidi rest easy.

Finding the arithmetic-geometric mean is an iterative process. Each step produces two numbers: the arithmetic and geometric means of the previous two numbers. So starting with, say, 1 and 2, the first step produces the two numbers 3/2 and √2. At the next step, you find the arithmetic mean of 3/2 and √2, which is approximately 1.457, and the geometric mean of 3/2 and √2, which is approximately 1.456. At that point, the two values you’re getting are already very close together, and subsequent iterations will produce two numbers that are arbitrarily close together. The limit of both the arithmetic and geometric means produced in this process is the same, so it is called the arithmetic-geometric mean. The arithmetic-geometric mean of 1 and 2 is 1.45679…; a bit disappointing in that it would be more fun if it started 1.456789, but a satisfying answer nonetheless.

The approximations of the arithmetic-geometric mean of two numbers get very close together very quickly, so the process has been used to find good approximations for irrational numbers, as in this paper about how to use it to approximate π.

What if you have more than two numbers? As far as I can tell, no one has ever defined the arithmetic-geometric mean for an arbitrary set of positive numbers, but that didn’t stop me. I’m not going to use the name arithmetic-geometric mean for the generalization to make sure nobody thinks it’s an “official” math term. Instead, I’ll call it the ditherer’s mean.

For the arithmetic-geometric mean of two numbers, we had an iterative process that gave us two numbers at every step. One way of thinking about it is that we replaced the smallest number with the geometric mean of the previous numbers and the largest number with the arithmetic mean of them. We’ll do the same thing for the ditherer’s mean.

To take the ditherer’s mean of n numbers, we want an iterative process that gives us n numbers at each step. So at each step, we replace the smallest number from the previous list of numbers with the geometric mean of the previous numbers and the largest number with the arithmetic mean of the numbers.

Let’s take a look at a set of 4 numbers to get a feel for how the process works. We’ll start with the numbers 1, 5, 20, and 26. The arithmetic mean of these numbers is 13, and the geometric mean is approximately 7.14. So we replace the largest and smallest numbers in our first list with 13 and 7.14. Now we have the numbers 5, 7.14, 13, and 20. We repeat the process. The arithmetic mean of those four numbers is about 11.285. The geometric mean is about 9.82. Now our list is 7.14, 9.82, 11.285, and 13. The arithmetic mean is 10.31 and the geometric mean is 10.07. Keep going: 9.82, 10.07, 10.31, 11.285. Then 10.07, 10.31, 10.35, 10.37. Progress! A few more iterations, and it’s clear the numbers are getting closer and closer together, landing around 10.3.

The arithmetic-geometric mean of two numbers has been a useful concept for mathematics. The iterative process that produces it converges very quickly, so it has been used to compute approximations quickly and accurately, as in this paper about computing π using the arithmetic-geometric mean. As far as I can tell, mathematicians have not yet found use for the ditherer’s mean, but I hope it will help some indecisive people take an average and move on with their lives.

There you have it: Now you can find an average of a set of positive numbers without having to choose between their arithmetic and geometric means. Isn’t it wonderful the way math always gives you a tidy answer with no room for uncertainty or ambiguity?

Wait, what’s that? Harmonic mean? Heronian mean? Identric mean? Nooooooooo!

For more insights like this, visit our website at www.international-maths-challenge.com.

Credit of the article given to Evelyn Lamb


The math behind the perfect free throw

Some 20 years ago, my colleague Dr. Chau Tran and I developed a way to simulate the trajectories of millions of basketballs on the computer.

We went to the coaches and assistant coaches at North Carolina State University, where we are based, and told them we had this uncommon ability to study basketball shots very carefully.

Their first question was simple: “What’s the best free throw?” Should the shooter aim towards the front of the hoop or the back? Does it depend on whether the shooter is short or tall?

Math offers a unique perspective. It speeds up the amount of time it takes to see the patterns behind the best shots. For the most part, we discovered things that the players and coaches already knew – but every so often, we came across a new insight.

Simulating millions of shots

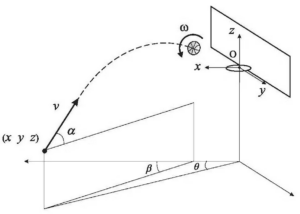
From a mathematical viewpoint, basketball is a game of trajectories. These trajectories are unique in that the ball’s motion doesn’t change much when it’s flying through the air, but then rapidly changes over milliseconds when the ball collides with the the hoop or the backboard.

To simulate millions of trajectories without the code taking too long to run, we tried any trick we could think of. We figured out how to go from modestly changing motion to rapidly changing motion, such as when the ball bounces on the rim or off the backboard. We learned how to turn large numbers of trajectories into statistical probabilities. We even created fictitious trajectories in which the ball magically passes through all of the physical obstacles (hoop, backboard, back plate) except for one, to see where it collides first.

How a mathematician sees a free throw. Larry Silverberg, CC BY-SA


The free throw was the first shot that my colleague and I studied in detail. In close games, teams can win and lose at the free-throw line. What’s more, the free throw is uncontested, so perfection in the free throw can pay off big. Top teams tend to shoot the free shot well.

Our program could tell us what chances the shooter had in sinking a free throw – and help us figure out what he was doing right or wrong.

Breaking down the free throw

We studied the free throw for about five years.

One of the first things we learned from our simulations and by watching TV footage was that players with the same consistency can shoot free throws with anywhere from 75 to 90 percent accuracy. The difference was that the 90 percent players were being consistent at the right shot – the best trajectory.

The fate of a free throw is set the instant the ball leaves the player’s fingertips, so we looked closely at the “launch conditions” of the shot. The ball is located at some height above the floor. It has a rate at which it is spinning backwards (called backspin), and it has a launch speed and a launch angle. Since the shooter never launches the ball the same way, small differences account for a shooter’s consistency.

We found that about 3 hertz of backspin is the best amount; more than that does not help. It takes about 1 second for a ball to reach the basket, so 3 hertz equates to three revolutions in the air, from the instant the ball leaves the player’s hands to when it reaches the basket.

Next, assuming the player releases the ball at 7 feet above the ground, a launch angle of about 52 degrees is best. In that angle, the launch speed is the lowest, and the probability of the shot being successful is the greatest. At 52 degrees, the shooter can be off a degree or more either way without a large effect on the shot’s success.

However, launch speed is quite the opposite. It’s the hardest variable for a player to control. Release the ball too slowly and the shot is short; release it too fast and the shot is long. A player needs to memorize the motion of her entire body during release to impart the same speed consistently.

All else being the same, players who release from higher above the floor have a higher shooting percentage. That’s interesting, because our coaches at N.C. State and others I have talked say that taller players tend to shoot the free throw worse than shorter players do. It seems that the shorter players must try harder.

The last release condition was the most surprising: the aim point of the free throw. We found that the player should aim the ball to the back of the rim. Basically, the back of the rim is more forgiving than the front of the rim. At a release height of 7 feet, the gap between the ball and the back of the ring should be less than 2 inches. A small gap is best whether launching at low or high release heights.

Lessons learned

So what does this all mean for players out there aspiring to improve their free throw?

Our research suggests that players should aim the ball beyond the center of the rim. Launch the ball at a high angle and as high above the ground as possible. (The ball, at the highest point of its arc, should reach the top of the backboard.) Line up the ball to eliminate the side angle. And try to launch the ball with smooth body motion, to produce a consistent launch speed.

In the past few years, we’ve expanded our work to study where the best bank shots strike the backboard and developed a tool for anyone who wants to perfect it.

With tournament play underway, I’m reminded of how competitive the game has become, and how it has truly become a game of inches. As an old basketball player, like many of you, I enjoy watching the game – and, every so often, catching a glimpse of that perfect free throw.

For more insights like this, visit our website at www.international-maths-challenge.com.
Credit of the article given to Larry M. Silverberg


“The Danger of a Single Story” in Mathematics

Credit: George Coppock Getty Images

The Lathisms podcast shares the varied stories of Hispanic and Latinx mathematicians

Writer Chimamanda Ngozi Adichie’s popular TED talk is called “The danger of a single story.” In it, she talks about the importance of reading and writing many stories of many people rather than putting a person—or an entire continent of people—into one box. “The single story creates stereotypes,” she says, “and the problem with stereotypes is not that they are untrue but that they are incomplete.”

If someone were asked to tell the story of a “typical” mathematician, they might talk about a shy, socially awkward white man who is a “genius,” whatever that means. He was a fast learner in school and can perform feats of calculation almost instantaneously in his head. He thinks about nothing other than his research, often to the detriment of practical tasks required for everyday living. Some mathematicians do fit these descriptions, but many more don’t. When that story becomes the dominant narrative of who mathematicians are, people who don’t fit the mold feel like there’s no place for them in mathematics. One of the great privileges of working as a math writer is getting to hear the stories of so many mathematicians when I talk to them for articles or podcasts. There really is no one kind of person who becomes a mathematician.

This fall, I’m happy to share a project, created by Lathisms and sponsored by a Tensor-SUMMA grant from the Mathematical Association of America, to share more stories of mathematicians. Lathisms was founded in 2016 by four Hispanic mathematicians, Alexander Diaz-Lopez, Pamela Harris, Alicia Prieto Langarica, and Gabriel Sosa. Hispanic and Latinx people are underrepresented in mathematics, and Lathisms aims to increase visibility of Hispanic and Latinx mathematicians. Since 2016, the organizers have created a calendar every Hispanic Heritage month (September 15-October 15) where each day has a different featured Hispanic or Latinx mathematician, including a picture and short biography of each of them.

This year, Lathisms decided to extend the celebration of Hispanic and Latinx mathematicians by adding a podcast, hosted by me, where you can listen to these mathematicians tell their stories in their own words. Starting at the end of August, we have published a new episode every Friday. The episodes feature mathematicians featured in past years’ Lathisms calendars as well as some of this year’s mathematicians. Some of them grew up in the U.S., others in Latin America. Some grew up in poverty, and others were better off. Some knew they wanted to be mathematicians from a young age, and others didn’t know anything about possible mathematics careers until college. Some work in pure math, others in applied. Some focus on research, others outreach.

So far we’ve shared conversations with Carlos Castillo-Chavez, who is one of the most prolific advisors of U.S. Latinx math Ph.D. students; Erika Camacho, who does mathematical modeling of eye diseases; Federico Ardila, who mentioned “the danger of a single story” when we talked and finds inspiration and mentorship from both students and teachers; and Nicolas Garcia Trillos, who just started a new job in the statistics department at the University of Wisconsin Madison and talked about the many ways there are to be a good mathematician and how that helps him get “unstuck” in his works. In the coming weeks, we will share many more stories. Tune in on Fridays to find them.

You can find the podcast at the Lathisms website or on iTunes. Transcripts are available already for some episodes and will be provided for all episodes. I hope these conversations will be helpful for teachers who want to make sure their students are aware of the diversity of mathematicians, for Hispanic and Latinx students and early-career mathematicians who are looking for role models and collaborators, and for anyone who wants to hear about mathematicians’ many different stories.

For more insights like this, visit our website at www.international-maths-challenge.com.

Credit of the article given to Evelyn Lamb


The genius at Guinness and his statistical legacy

This St Patrick’s Day, revellers around the world will crowd the streets seeking one of Ireland’s national drinks: a pint of Guinness. But besides this tasty stout, one of the most fundamental and commonly used tools of science also has its origins at the Guinness brewery.

Towards the end of the 19th century, Guinness was scaling up its operations, and was interested in applying a scientific approach to all aspects of Guinness production: from barley growth right through to the Guinness taste.

Before adopting a scientific approach, brewers at Guinness relied on subjective methods, such as the appearance and scent of hops, to assess produce quality.

Once scientific brewers were recruited, a more objective approach was taken. The first scientific brewer, Thomas Bennett Case, was hired in 1893 and he believed that the amount of soft resins in hops was related to the quality of Guinness. He was therefore keen to estimate the amount of soft resin in particular crops of hops.

The challenge facing Case was that he, like any scientist, could not measure everything at once. It was not possible for him to assess the amount of soft resin in every single one of the countless hop flowers (added by the thousands to enormous vats of soon-to-be Guinness) in his charge.

Instead, he took a sample of hops (11 measurements of 50 grams each) and calculated the average soft resin content. His hope was that the average soft resin content of his small sample could be used to estimate the soft resin content of the entire crop (what statisticians would call “the population”) of hops.

For comparison, a colleague took a further 14 measurements of 50 grams each from the same lot of hops. Case found a small difference in the average amount of soft resins between these samples.

He was stumped. Were these differences in hop content due to real differences across the whole hop crop, or were they due to random error introduced by using small sample sizes?

Size matters

At the time, statistics relied on what is called “large-sample theory”, which unsurprisingly requires large samples (150 or more) to work. Applying it to problems involving small samples (like those faced by Case at Guinness) was difficult.

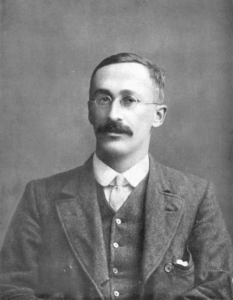
William Sealy Gosset. Wikimedia

This was the problem that William Sealy Gosset, a recent graduate of chemistry and mathematics at Oxford University, was keen to address. Gosset began work as an apprentice brewer at the Guinness factory in Dublin in 1899.

In 1906, Gosset, now a self-taught statistician, went to study with Karl Pearson, a leading figure in statistics, at University College London.

Gosset was keen to adapt Pearson’s large-sample methods to deal with the small samples they used at Guinness. There, he developed his ideas and readied them for publication.

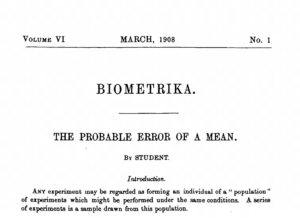
However, until the late 1930s, Guinness would not allow employees to publish under their own names for fear that other brewers would learn of their scientific approaches to beer. As a result, Gosset published his most important paper, The Probable Error of a Mean, under the pseudonym “Student” in the journal Biometrika in 1908.

The ultimate ‘Student’ author’s journal paper. Biometrika (screen grab)


This was the origin of Student’s t-test, a fundamental statistical method that is widely used to this day.

Student’s t-test

The problem that Case faced was that using small samples of hops introduces a new source of uncertainty into the analysis, leaving him less able to distinguish between real, true differences between two batches of hops and differences due to this uncertainty.

Gosset’s genius was to devise a way of accounting for this: the t-distribution. This mathematically defines the relationship between the size of sample and the amount of uncertainty this imposes.

Basically, when carrying out experiments, the t-distribution (and the famous t-test that depends upon it) allows beer brewers and scientists alike to account for the size of the sample they have used in their work, and then define just how confident they are in their findings.

Sticking with the brewers’ case, you would have information from the two samples, such as the average soft resin content of the hops and the spread of each measurement around the average of each sample.

Without going into too much detail, the t-test helps to determine whether there is evidence of a difference between the two averages based on the sample size (that is, the number of measurements taken from a particular hop crop). In the brewers’ case they were looking for zero difference between their two samples.

A lasting legacy

Gosset’s method did not draw the attention of the statistical community until another leading statistical figure, Ronald Aylmer Fisher, enthusiastically embraced the method and provided a mathematical proof.

Since that time, the t-test has been used to tackle a huge range of scientific problems, from the assessment of brain function in stroke patients , to the measurement of carbon and nitrogen content in coastal ocean-dwelling bacteria, to how the behaviour of coal miners may or may not lead to accidents (the consumption of Guinness by these miners was, perhaps unsurprisingly, not a focus of the study).

In fact, Student’s t-test has been employed in essentially every field of scientific endeavour: biology, physics, psychology, biometrics, economics and medicine.

It is a staple of undergraduate statistics taught across these disciplines, but few may be aware of Gosset’s role in creating the t-test and his beery reasons for doing so.

Gosset remained at Guinness throughout his life as Head Experimental Brewer, then Head of the Statistics Department he formed at Guinness, before his promotion to Head Brewer for the new Guinness brewery in London in 1935. He published several papers as “Student” but his true identity was only publicly revealed upon his death in 1937.

So, if you’re drinking a Guinness this St Patrick’s day, raise a glass to the little-known character who played a pivotal role in beer, statistics and indeed, modern science: William Sealy Gosset.

For more insights like this, visit our website at www.international-maths-challenge.com.
Credit of the article given to Karen Lamb, David Farmer


Pi in the Sky

Elegant new visualization maps the digits of pi as a star catalogue

The mind of Martin Krzywinski is a rich and dizzying place, teeming with fascinating questions, ideas, and inspiration. Krzywinski is a scientist and data visualizer whose primary line of work involves genome analysis for cancer research. In his spare time, though, he explores his many different interests as a scientific and visual thinker through creative projects. For the past few years, one such project has occupied him on a recurring basis each March: reimagining the digits of pi in a novel, science-based, and visually compelling way.

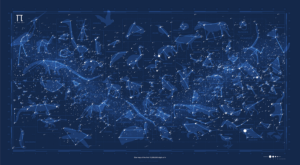
Today, this delightful March 14th (“Pi Day”) tradition brings us the digits of pi mapped onto the night sky, as a star catalogue. Like the infinitely long sequence of pi, space has no discernible end, but we earthbound observers can only see so far. So Krzywinski places a cap at 12 million digits and groups each successive series of 12 numerals to define a latitude, longitude and brightness, resulting in a field of a million stars, randomly arranged.

Just as humans throughout history have found figures and narratives among the stars, this new array of celestial bodies also yields a story. As a way to honor our evolutionary ancestors, Krzywinski connects the dots to create shapes of extinct animals from around the globe.

Carée projection of “Pi in the Sky” star chart
Credit: Martin Krzywinski

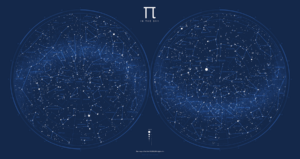
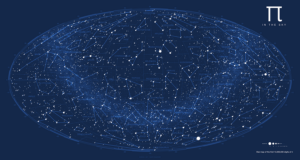
But he couldn’t possibly stop there, so Krzywinski takes the visualization a step further, experimenting with different projections to re-create the map in various spatial iterations.

Azimuthal projections of “Pi in the Sky” star chart
Credit: Martin Krzywinski

Hammer/Aitoff projection of “Pi in the Sky” star chart
Credit: Martin Krzywinski

To read more about the visualization, including descriptions of the animals depicted, and a poem written by the artist’s collaborator Paolo Marcazzan, visit Martin Krzywinski’s website. There, you can also explore his previous Pi Day visualizations and even purchase them as posters.

For more insights like this, visit our website at www.international-maths-challenge.com.

Credit of the article given to Amanda Montañez


On his 250th birthday, Joseph Fourier’s math still makes a difference

March 21 marks the 250th birthday of one of the most influential mathematicians in history. He accompanied Napoleon on his expedition to Egypt, revolutionized science’s understanding of heat transfer, developed the mathematical tools used today to create CT and MRI scan images, and discovered the greenhouse effect.

His name was Joseph Fourier. He wrote of mathematics: “There cannot be a language more universal and more simple, more free from errors and obscurities … Mathematical analysis is as extensive as nature itself, and it defines all perceptible relations.” Fourier’s work continues to shape life today, especially for people like ourselves working in fields such as mathematics and radiology.

Fourier’s life

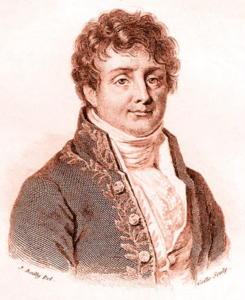
Mathematician and physicist Joseph Fourier. Wikimedia Commons

As a troubled orphan in France, Fourier was transformed by his first encounter with mathematics. Thanks to a local bishop who recognized his talent, Fourier received an education through Benedictine monks. As a college student, he so loved math that he collected discarded candle stumps so he could continue his studies after others had gone to bed.

As a young man, Fourier was soon swept up by the French Revolution. However, he became disenchanted by its excessive brutality, and his protests landed him in prison for part of 1794. After his release, he was appointed to the faculty of an engineering school. There he proved his genius by substituting for ill colleagues, teaching subjects ranging from physics to classics.

Traveling with Napoleon to Egypt in 1798, Fourier was appointed secretary of the Egyptian Institute, which Napoleon modeled on the Institute of France. When the British fleet stranded the French forces, he organized the manufacture of weapons and munitions to permit the French to continue fighting. Fourier returned to France after the British navy forced the French to surrender. Even in the midst of such difficult circumstances, he managed to publish a number of mathematical papers.

Heat transfer

One of the most important fruits of Fourier’s studies concerns heat.

Fourier’s law states that heat transfers through a material at a rate proportional to both the difference in temperature between different areas and to the area across which the transfer takes place. For example, people who are overheated can cool off quickly by getting to a cool place and exposing as much of their body to it as possible.

Fourier’s work enables scientists to predict the future distribution of heat. Heat is transferred through different materials at different rates. For example, brass has a high thermal conductivity. Air is poorly conductive, which is why it’s frequently used in insulation.

Remarkably, Fourier’s equation applies widely to matter, whether in the form of solid, liquid or gas. It powerfully shaped scientists’ understanding of both electricity and the process of diffusion. It also transformed scientists’ understanding of flow in nature generally – from water’s passage through porous rocks to the movement of blood through capillaries.

Fourier transform and CT

Today, when helping to care for patients, radiologists rely on another mathematical discovery of Fourier’s, now referred to as the “Fourier transform.”

In CT scans, doctors send X-ray beams through a patient from multiple different directions. Some X-rays emerge from the other side, where they can be measured, while others are blocked by structures within the body.

Modern medical imaging machines rely on Fourier’s transform. zlikovec/shutterstock.com

With many such measurements taken at many different angles, it becomes possible to determine the degree to which each tiny block of tissue blocked the beam. For example, bone blocks most of the X-rays, while the lungs block very little. Through a complex series of computations, it’s possible to reconstruct the measurements into two-dimensional images of a patient’s internal anatomy.

Thanks to Fourier and today’s powerful computers, doctors can create almost instantaneous images of the brain, the pulmonary arteries, the appendix and other parts of the body. This in turn makes it possible to confirm or rule out the presence of issues such as blood clots in the pulmonary arteries or inflammation of the appendix. It’s difficult to imagine practicing medicine today without such CT images.

Greenhouse effect

Fourier is generally regarded as the first scientist to notice what we today call the greenhouse effect.

His interest was piqued when he observed that a planet as far away from the sun as Earth should be considerably cooler. He hypothesized that something about the Earth – in particular, its atmosphere – must enable it to trap solar radiation that would otherwise simply radiate back out into space.

Fourier created a model of the Earth involving a box with a glass cover. Over time, the temperature in the box rose above that of the surrounding air, suggesting that the glass continually trapped heat. Because his model resembled a greenhouse in some respects, this phenomenon came to be called the “greenhouse effect.”

Later, scientist John Tyndall discovered that carbon dioxide can play the role of heat trapper.

Life on earth as we know it would not be possible without the greenhouse effect. However, today scientists tend to be more concerned about an excess of greenhouse gases. Mathematical models suggest that as carbon dioxide accumulates, heat may be trapped more quickly, resulting in elevated global average temperatures, melting polar ice caps and rising sea levels.

Fourier’s impact

Fourier received many honors during his lifetime, including election to the French Academy of Science.

Some believed, perhaps speciously, that Fourier’s attraction to heat may have hastened his death. He was known to climb into saunas in multiple layers of clothes, and his acquaintances claimed that he kept his rooms hotter than Hades. At any rate, in May 1830, he died of an aneurysm at the age of 63.

Today, Fourier’s name is inscribed on the Eiffel Tower. But more importantly, it is immortalized in Fourier’s law and the Fourier transform, enduring emblems of his belief that mathematics holds the key to the universe.

For more insights like this, visit our website at www.international-maths-challenge.com.
Credit of the article given to Richard Gunderman, David Gunderman


Peculiar Pattern Found in “Random” Prime Numbers

Credit: ©iStock.com

Last digits of nearby primes have “anti-sameness” bias

Two mathematicians have found a strange pattern in prime numbers—showing that the numbers are not distributed as randomly as theorists often assume.

“Every single person we’ve told this ends up writing their own computer program to check it for themselves,” says Kannan Soundararajan, a mathematician at Stanford University in California, who reported the discovery with his colleague Robert Lemke Oliver in a paper submitted to the arXiv preprint server on March 11. “It is really a surprise,” he says.

Prime numbers near to each other tend to avoid repeating their last digits, the mathematicians say: that is, a prime that ends in 1 is less likely to be followed by another ending in 1 than one might expect from a random sequence. “As soon as I saw the numbers, I could see it was true,” says mathematician James Maynard of the University of Oxford, UK. “It’s a really nice result.”

Although prime numbers are used in a number of applications, such as cryptography, this ‘anti-sameness’ bias has no practical use or even any wider implication for number theory, as far as Soundararajan and Lemke Oliver know. But, for mathematicians, it’s both strange and fascinating.

Not so random

A clear rule determines exactly what makes a prime: it’s a whole number that can’t be exactly divided by anything except 1 and itself. But there’s no discernable pattern in the occurrence of the primes. Beyond the obvious—after the numbers 2 and 5, primes can’t be even or end in 5—there seems to be little structure that can help to predict where the next prime will occur.

As a result, number theorists find it useful to treat the primes as a ‘pseudorandom’ sequence, as if it were created by a random-number generator.

But if the sequence were truly random, then a prime with 1 as its last digit should be followed by another prime ending in 1 one-quarter of the time. That’s because after the number 5, there are only four possibilities—1, 3, 7 and 9—for prime last digits. And these are, on average, equally represented among all primes, according to a theorem proved around the end of the nineteenth century, one of the results that underpin much of our understanding of the distribution of prime numbers. (Another is the prime number theorem, which quantifies how much rarer the primes become as numbers get larger.)

Instead, Lemke Oliver and Soundararajan saw that in the first billion primes, a 1 is followed by a 1 about 18% of the time, by a 3 or a 7 each 30% of the time, and by a 9 22% of the time. They found similar results when they started with primes that ended in 3, 7 or 9: variation, but with repeated last digits the least common. The bias persists but slowly decreases as numbers get larger.

The k-tuple conjecture

The mathematicians were able to show that the pattern they saw holds true for all primes, if a widely accepted but unproven statement called the Hardy–Littlewood k-tuple conjecture is correct. This describes the distributions of pairs, triples and larger prime clusters more precisely than the basic assumption that the primes are evenly distributed.

The idea behind it is that there are some configurations of primes that can’t occur, and that this makes other clusters more likely. For example, consecutive numbers cannot both be prime—one of them is always an even number. So if the number n is prime, it is slightly more likely that n + 2 will be prime than random chance would suggest. The k-tuple conjecture quantifies this observation in a general statement that applies to all kinds of prime clusters. And by playing with the conjecture, the researchers show how it implies that repeated final digits are rarer than chance would suggest.

At first glance, it would seem that this is because gaps between primes of multiples of 10 (20, 30, 100 and so on) multiples of 10 are disfavoured. But the finding gets much more general—and even more peculiar. A prime’s last digit is its remainder when it is divided by 10. But the mathematicians found that the anti-sameness bias holds for any divisor. Take 6, for example. All primes have a remainder of 1 or 5 when divided by 6 (otherwise, they would be divisible by 2 or 3) and the two remainders are on average equally represented among all primes. But the researchers found that a prime that has a remainder of 1 when divided by 6 is more likely to be followed by one that has a remainder of 5 than by another that has a remainder of 1. From a 6-centric point of view, then, gaps of multiples of 6 seem to be disfavoured.

Paradoxically, checking every possible divisor makes it appear that almost all gaps are disfavoured, suggesting that a subtler explanation than a simple accounting of favoured and disfavoured gaps must be at work. “It’s a completely weird thing,” says Soundararajan.

Mystifying phenomenon

The researchers have checked primes up to a few trillion, but they think that they have to invoke the k-tuple conjecture to show that the pattern persists. “I have no idea how you would possibly formulate the right conjecture without assuming it,” says Lemke Oliver.

Without assuming unproven statements such as the k-tuple conjecture and the much-studied Riemann hypothesis, mathematicians’ understanding of the distribution of primes dries up. “What we know is embarrassingly little,” says Lemke Oliver. For example, without assuming the k-tuple conjecture, mathematicians have proved that the last-digit pairs 1–1, 3–3, 7–7 and 9–9 occur infinitely often, but they cannot prove that the other pairs do. “Perversely, given our work, the other pairs should be more common,” says Lemke Oliver.

He and Soundararajan feel that they have a long way to go before they understand the phenomenon on a deep level. Each has a pet theory, but none of them is really satisfying. “It still mystifies us,” says Soundararajan.

For more insights like this, visit our website at www.international-maths-challenge.com.

Credit of the article given to Evelyn Lamb & Nature magazine